Table of contents
Google won’t index every page it finds, and poor crawlability is often why. You publish a page, resubmit it in the Search Console, and wait. Weeks later, it’s still missing from Google.
Meanwhile, customers find your competitors instead. No rankings means no clicks, leads, or sales. Worse, one wrong setting can quietly hide your whole site.
Crawlability lets Google’s bots find and read your pages. Indexability decides whether Google stores and shows them. Below, you’ll learn to check both in Search Console and fix 6 common blockers. You’ll also see when to use robots.txt, noindex, or canonical tags. Plus, you’ll learn how to stay visible in AI tools like ChatGPT.
Key Points:
- Crawlability means search engine bots can find and read your page, while indexability means Google can store it and show it in results.
- A page must be crawled before it can be indexed, but Google doesn’t index every page it crawls.
- Common blockers include robots.txt rules, stray noindex tags, broken links, orphan pages, duplicate URLs, and content hidden behind JavaScript.
- Use robots.txt to stop crawling, noindex to keep a page out of search, and canonical tags to merge duplicate pages.
- Google Search Console, Bing Webmaster Tools, and Screaming Frog can spot most crawlability issues for free.
- AI search tools like ChatGPT can cite your pages only if your robots.txt allows their search crawlers, like OAI-SearchBot.
What Is Crawlability?
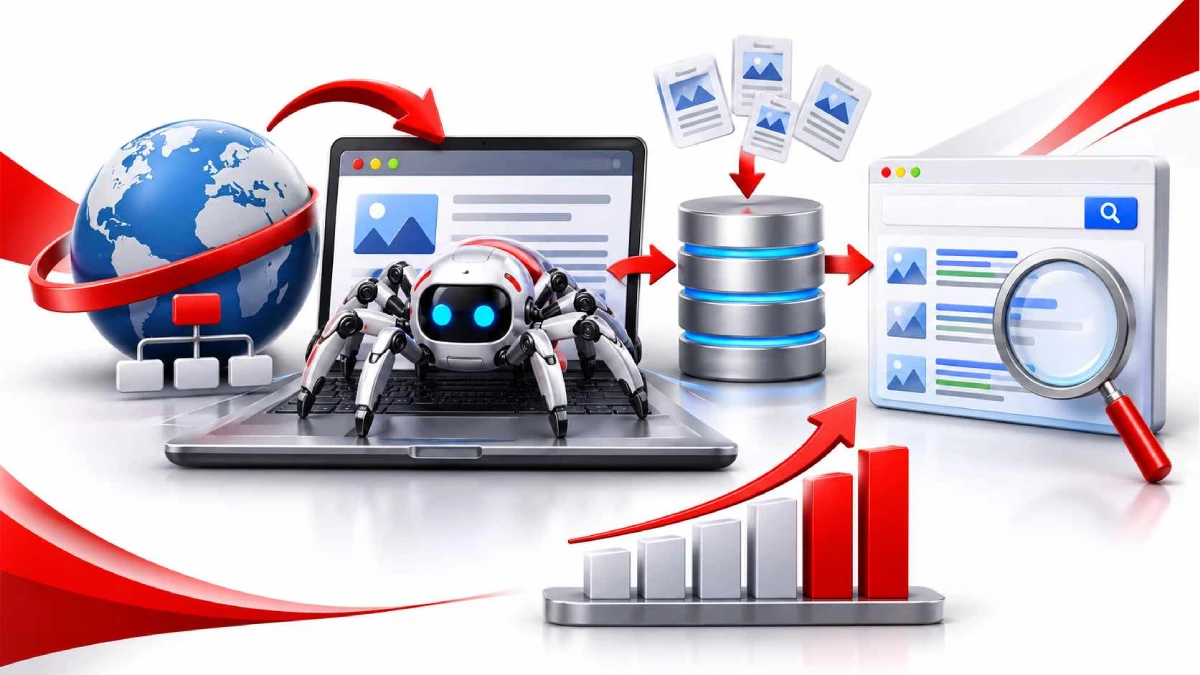
Crawlability is how easily search engine bots can find, reach, and read the pages on your website. Bots like Googlebot and Bingbot visit your pages, read the code, and follow links to new pages. If a bot can’t reach a page, that page stays in visible to search.
Think of crawlability as the front door of your shop. If you lock the door, nobody walks in, no matter how good your products are. That’s why it’s the first step of technical SEO, before indexing and ranking.
What Makes a Page Crawlable?
A page is crawlable when bots can find it through a link or sitemap, robots.txt allows the visit, and the page returns a 200 OK status. Errors like 404 or 500 stop the bot, and orphan pages with no links pointing to them stay hidden. Size matters too, since Googlebot reads only the first 2MB of an HTML file when crawling for Google Search.
What Is a Crawlable Link?
A crawlable link is a standard HTML <a> tag with a real URL in its href, like <a href=”/running-shoes”>Running shoes</a>. Links built only with JavaScript click events, like <a onclick=”goTo()”>, give bots no URL to follow. So use real <a href> links for menus, product grids, and pagination.
What Is Indexability?
Indexability is whether a search engine can store your page in its index after crawling it. Only indexed pages can appear in results on Google, Bing, or DuckDuckGo. That index is huge, since Google’s covers hundreds of billions of webpages and exceeds 100,000,000 gigabytes.
Think of the index as a library catalog. Crawlability gets the book through the door, and indexability decides if it goes on the shelf. However, Google doesn’t shelve everything it reads, so a crawled page can still be left out.
What Makes a Page Indexable?
A page is indexable when it has no noindex tag, a correct canonical tag, a 200 OK status, and useful, original content. Blockers include a noindex meta tag, an X-Robots-Tag: noindex header, or a canonical pointing to another URL. Google also skips thin, duplicate, or soft 404 pages, like empty tag archives or “no products found” pages.
What Is the Difference Between Crawlability and Indexability?
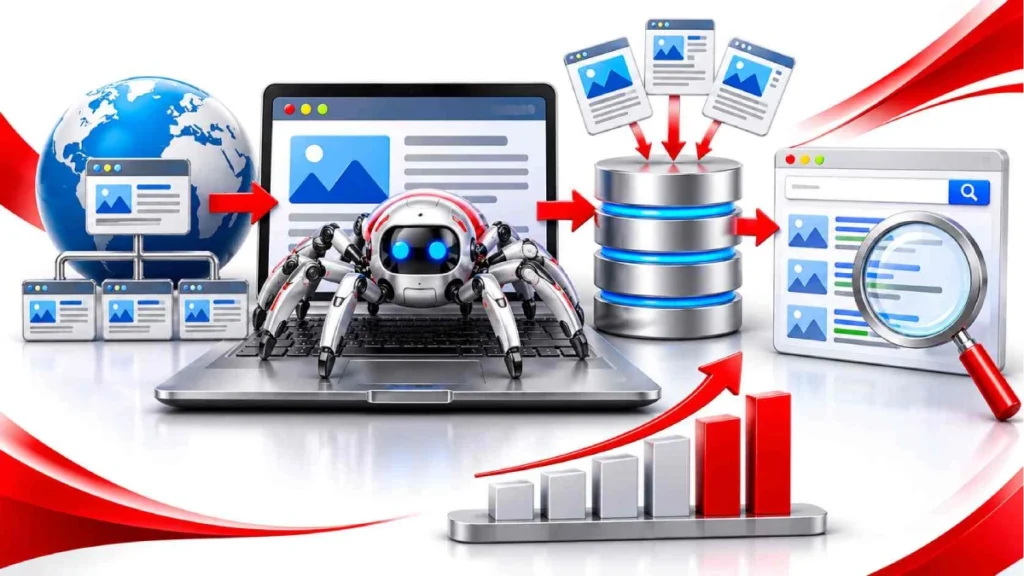
Crawlability is about whether bots can reach your page, while indexability is about whether Google stores it. Crawling always comes first, since Google can’t index a page it never reached. However, Google does not guarantee indexing, and it may not index every page it processes.
Picture a job application. Crawlability gets your CV onto the recruiter’s desk, and indexability decides if it goes into the shortlist folder. Even then, ranking is a third step, where Google picks the most relevant pages for each search.
| Crawlability | Indexability | |
| Question it answers | Can bots reach and read the page? | Will Google store the page? |
| Controlled by | Links, sitemaps, robots.txt, server health | Noindex tags, canonical tags, content quality |
| Common blockers | Robots.txt blocks, 404 and 500 errors, orphan pages | Noindex tags, duplicate pages, thin content |
| Where to check | URL Inspection, robots.txt report, crawl tools like Screaming Frog | Search Console Pages report, URL Inspection |
How to Check If Your Site Is Crawlable and Indexed
You can check your site’s crawlability and indexing for free with Google Search Console and a few quick manual tests. Search Console shows what Google actually crawled and stored. Crawl tools like Screaming Frog show what bots can reach right now.
Start with the quick check below for any single page. Then use the Pages report to see the full picture across your site. Together, they show where a page gets stuck.
The 5-Minute Quick Check
Paste your URL into Search Console’s URL Inspection tool and click “Test Live URL.” It shows if Google can crawl the page and if anything blocks indexing. Also open yourdomain.com/robots.txt and look for blocks like Disallow: /.
Understanding the Search Console Pages Report
The Pages report shows which URLs Google indexed and why Google left others out. “Discovered – currently not indexed” means Google found the page but hasn’t crawled it yet. “Crawled – currently not indexed” means Google read it but chose not to store it, often due to thin content.
Why Isn’t My Page on Google? Common Crawlability Problems and Fixes
Most pages miss Google because a technical block, a missing link, or low-value content stops them. The cause usually falls into 1 of 6 common problems. Each one leaves a clear clue in Search Console or your site’s code.
Work through them in order, starting with the simplest checks. A single robots.txt line or stray noindex tag can hide a whole site. Fixing crawlability issues first saves you from chasing the wrong problem.
Robots.txt Blocking Important Pages
A wrong robots.txt rule can stop Googlebot from visiting your key pages. For example, Disallow: /products/ blocks every product page in that folder. Also check that CSS and JavaScript files stay unblocked, so Google can load your pages properly.
Accidental Noindex Tags
A noindex tag tells Google to keep a page out of search results. It often slips in from staging sites or plugin settings, like WordPress’s “Discourage search engines” box. Check your source code for <meta name=”robots” content=”noindex”> after every site launch.
Broken Links, Redirect Chains, and Server Errors
Broken links, long redirect chains, and server errors waste Google’s crawl visits. Googlebot generally follows up to 10 redirect hops, so point old URLs straight to the final page with one 301 redirect. Also fix 404 links and repeated 500 or 503 errors quickly.
Orphan Pages and Weak Internal Links
Orphan pages have no internal links pointing to them, so bots struggle to find them. Even a page in your sitemap gets less attention without links. Link each important page from related content, like blog posts, category pages, or your main menu.
Duplicate Content and Canonical Issues
Duplicate pages make Google pick one version and skip the rest. URL parameters like ?sort=price or ?color=blue often create copies of the same page. Add a canonical tag pointing to the main URL, and remember Google treats it as a hint, not a rule.
Content Hidden Behind JavaScript
Content that loads only through JavaScript may be missed or indexed late. Google renders JavaScript in a separate step, which can delay what it sees. Use server-side rendering or static pages so key text and links appear in the raw HTML.
Robots.txt vs. Noindex vs. Canonical: Which Should You Use?
Use robots.txt to stop crawling, noindex to keep a page out of search, and canonical to merge duplicate pages. Each tool solves a different problem, so mixing them up causes trouble. For example, blocking a page in robots.txt won’t reliably remove it from Google.
The biggest mistake is combining robots.txt and noindex on the same page. Google says a noindex rule only works if robots.txt doesn’t block the page. Otherwise, the crawler never sees the rule, and the page can still appear in results if other sites link to it.
| Robots.txt | Noindex | Canonical | |
| What it does | Stops bots from crawling a page or folder | Keeps a page out of search results | Tells Google which duplicate is the main version |
| Does Google crawl the page? | No | Yes, it must | Yes, it must |
| Best for | Admin areas, internal search results, cart pages | Thank-you pages, login pages, thin tag archives | Filtered URLs, tracking parameters, product variants |
| Example | Disallow: /wp-admin/ | <meta name=”robots” content=”noindex”> | <link rel=”canonical” href=”https://site.com/shoes”> |
Also, Google doesn’t support noindex rules inside robots.txt, so place them in the page’s head or HTTP header. And remember, robots.txt is public, so never use it to hide private pages. Use a password instead.
How to Improve Crawlability and Indexability
You improve crawlability and indexability by making key pages easy to reach, fast to load, and worth indexing. Start with the pages that bring you customers, like service pages, product pages, and top blog posts. Then work outward to the rest of your site.
Small fixes often matter more than big rebuilds. A few new internal links or a cleaner sitemap can get stuck pages indexed. Here are the steps that make the biggest difference:
- Keep a flat site structure. Put important pages within 3 clicks of your homepage, like Home > Services > Roof Repair.
- Add internal links. Link new pages from related content, like blog posts, category pages, or your main menu.
- Clean your XML sitemap. List only live, indexable pages that return 200 OK, with accurate <lastmod> dates.
- Speed up your server. Use reliable hosting and a CDN like Cloudflare, so Googlebot can crawl more pages per visit.
- Remove or merge thin pages. Delete or combine empty tag archives, old promo pages, and near-duplicate posts.
- Add hreflang for multiple languages. Tell Google which page serves English, Norwegian, or Spanish users.
Does Crawl Budget Matter for Small Sites?
No, crawl budget rarely matters for small business sites. Google’s crawl budget guide targets sites with 1 million+ pages that change weekly, or 10,000+ pages that change daily. For smaller sites, Google says keeping your sitemap updated and checking your Page Indexing report regularly is enough.
Can You Get Google to Crawl Your Site Faster?
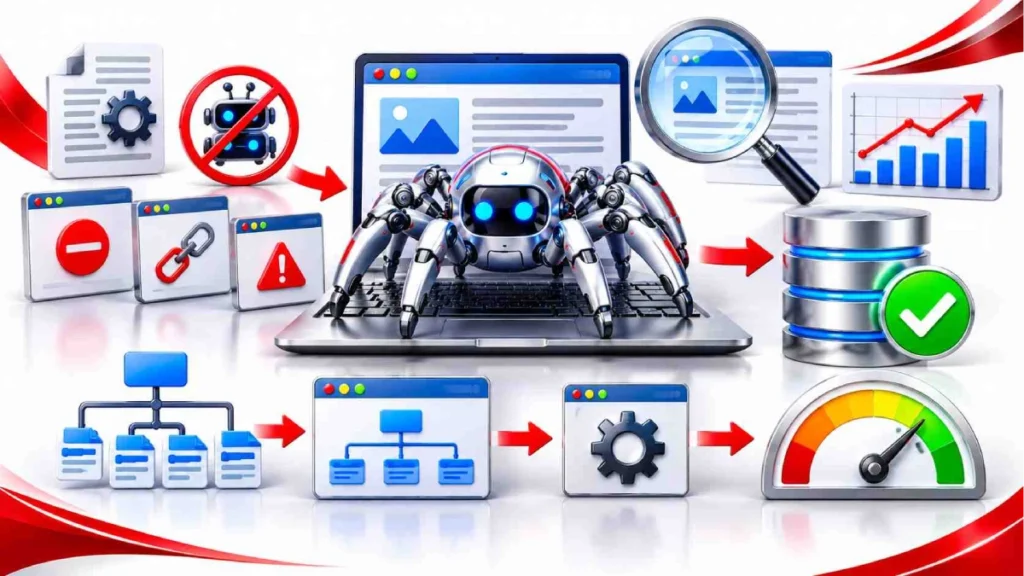
No, you can’t force Google to crawl your site, but you can ask it to visit sooner. Use the URL Inspection tool in Search Console to request indexing for 1 page, or submit an XML sitemap for many pages. Google says crawling can take a few days to a few weeks, and a request doesn’t guarantee indexing.
Links from strong pages, like your homepage or a popular blog post, also help Googlebot find new pages faster. For Bing and Yandex, IndexNow sends instant updates, but Google doesn’t support it. If a page still won’t get indexed, check it for thin content, a noindex tag, or a wrong canonical.
Crawlability for AI Search Tools
AI search tools like ChatGPT, Perplexity, and Claude can only cite your pages if their crawlers can reach them. Each company runs separate bots for training and for search, like OpenAI’s GPTBot and OAI-SearchBot. OpenAI treats each robots.txt setting independently, so you can block training and still appear in ChatGPT search.
For example, User-agent: GPTBot with Disallow: / blocks training, while leaving OAI-SearchBot and Claude-SearchBot open keeps you citable. Note that Google’s AI Overviews use regular Googlebot, so blocking Google-Extended won’t remove you from them. Also, many AI crawlers don’t run JavaScript, so keep key text and links in your raw HTML.
Tools and Crawlability Checklist
The best free tools for checking crawlability are Google Search Console, Bing Webmaster Tools, and Screaming Frog. Search Console shows what Google actually crawled and indexed, while Bing Webmaster Tools does the same for Bing. Screaming Frog crawls your site like a bot, and its free version handles up to 500 URLs.
For larger sites, paid tools like Sitebulb, Semrush Site Audit, and Ahrefs Site Audit add scheduled scans. Run a full check after every launch, redesign, or plugin update, and at least once a month. Use this checklist each time:
- Robots.txt allows key pages, plus CSS and JavaScript files
- No stray noindex tags on important pages
- Key pages return 200 OK, with no 404 or 500 errors
- Redirects go straight to the final URL in 1 hop
- Every indexable page has a correct canonical tag
- Menus and content use real <a href> links
- Important pages stay within three clicks of the homepage.
- No orphan pages without internal links
- Sitemap lists only live, indexable URLs
- Key text and links appear in the raw HTML
- Allow AI search bots like OAI-SearchBot if you want citations.
FAQs
Does page speed affect crawlability?
Yes, page speed affects crawlability because faster servers let Googlebot crawl more pages per visit. Slow responses and repeated 5xx errors cause Google to reduce its crawl rate for the site.
Does robots.txt remove a page from Google?
No, robots.txt only stops crawling and does not reliably remove a page from Google’s index. To remove a page, allow crawling and add a noindex tag so Google can read it.
Is a crawlability audit worth it for a small website?
Yes, a crawlability audit is worth it for a small website because a single blocked folder or stray noindex tag can hide key pages. Free tools such as Google Search Console and Screaming Frog handle most small-site SEO checks without extra cost.
Is crawlability the same as searchability or googleability?
No, crawlability means bots can reach and read a page, while searchability and googleability describe how easily people find it in search. Crawlability is the first step, followed by indexing and ranking.
How Long Does Google Take to Index a New Page?
Google may take several days or weeks to crawl and index a new page. Internal links from strong pages and an updated XML sitemap help Google find the page sooner.
What Happens If You Accidentally Block Googlebot?
If you block Googlebot in robots.txt, Google stops crawling your pages and they gradually lose visibility in search results. Removing the block and testing the URL in Search Console restores crawling on Google’s next visits.
Can blocking AI crawlers hurt my Google rankings?
No, blocking AI training crawlers like GPTBot or the Google-Extended token does not affect Google Search rankings. Blocking Googlebot itself, however, removes your pages from both Google Search and AI Overviews.
Is an llms.txt File Necessary for AI Search?
No, an llms.txt file is not required for AI search, and major search engines do not officially rely on it. Allowing AI search crawlers in robots.txt and keeping content in raw HTML matter more for AI visibility.
Conclusion:
Crawlability decides whether search engine bots can reach your pages. Indexability decides whether Google stores them. A page needs both to rank in search results. Most problems come from a few common causes, like robots.txt blocks, stray noindex tags, and broken links. Orphan pages, duplicate URLs, and content hidden behind JavaScript cause trouble too.
Google Search Console, a quick robots.txt review, and a free Screaming Frog crawl can spot most issues. Fix blockers first. Then strengthen internal links, clean your sitemap, and remove thin pages. Keep AI search bots like OAI-SearchBot open if you want ChatGPT citations. And don’t worry about crawl budget unless your site has thousands of fast-changing pages.
Open Google Search Console today and inspect your 5 most important pages. Then fix anything that stops them from appearing on Google.
Need a hand with this?
I do this work for a small number of clients each quarter. A 30-minute call is free and you'll get three specific fixes whether or not we work together.
Usama Habib
AI SEO Specialist & SEO Consultant. I help businesses win visibility in Google and in AI search, and I publish everything I learn as complete topical maps.