Table of contents
Without JavaScript SEO, your site can look complete in a browser but appear empty to Google. W3Techs reports that 98.9% of all websites use JavaScript. Many of these sites send crawlers a nearly blank page, costing rankings and leads.
Google can run JavaScript, but rendering can fail when scripts time out or content hides behind clicks. AI crawlers like GPTBot and PerplexityBot may not execute JavaScript, so content missing from the raw HTML may remain unseen.
This guide explains how Google crawls, renders, and indexes JavaScript pages. You’ll compare CSR, SSR, SSG, and dynamic rendering, then pick the right setup. You’ll also get best practices, 4 simple tests, a checklist, common fixes, and developer tips.
Key Points:
- JavaScript SEO helps search engines and AI tools access content that loads through JavaScript. Problems start when text, links, or tags appear only after scripts run.
- Google can render JavaScript, but many AI crawlers may not. GPTBot, ClaudeBot, and PerplexityBot may rely on raw HTML, leaving client-side content inaccessible.
- Server-side rendering (SSR) and static site generation (SSG) are the safest setups for public pages. Google calls dynamic rendering a workaround, not a long-term fix.
- Key SEO elements must be in the raw HTML. This includes real <a href> links, titles, canonicals, structured data, and proper 404 status codes.
- Four quick tests show what Google sees. Use URL Inspection, a site: search, a JavaScript-off browser check, and a JavaScript-rendering crawl.
- Clear, testable requests help developers fix issues faster. Give them one problem, one fix, and one way to confirm it works.
What Is JavaScript SEO?
JavaScript SEO makes sure search engines and AI tools can find, read, and index your JavaScript content. JavaScript runs the interactive parts of a site, like menus, filters, and pop-up forms. W3Techs reports that 98.9% of all websites use JavaScript, including every site on WordPress, Shopify, and Wix.
So using JavaScript isn’t the problem. The trouble starts when your main content, like text, links, and product details, needs JavaScript to appear. Google can render that content later, but most AI crawlers, like GPTBot and PerplexityBot, never do.
How Google Crawls, Renders, and Indexes JavaScript
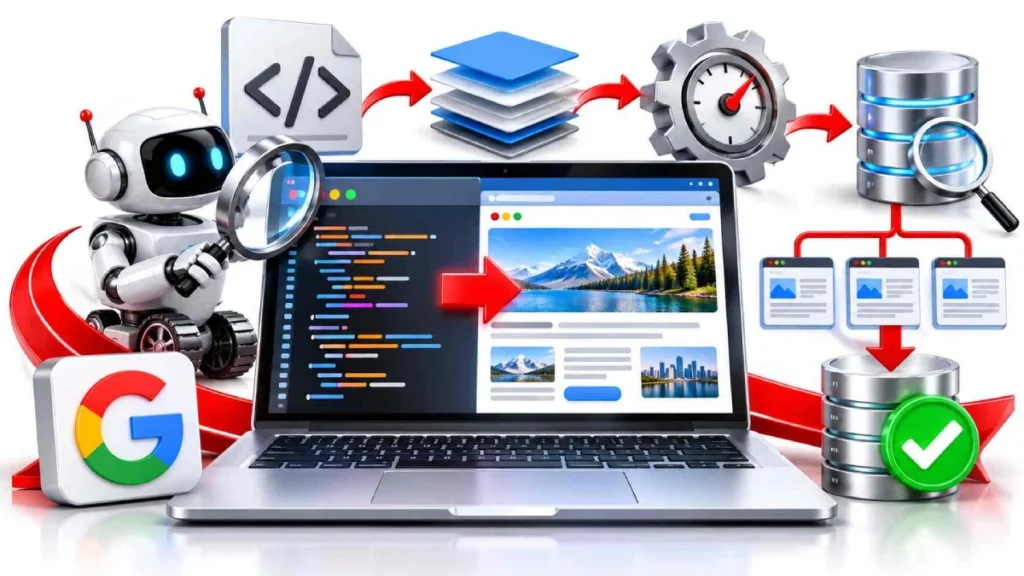
Google processes JavaScript pages through three stages: crawling, rendering, and indexing. Googlebot first downloads your raw HTML and collects any links it finds. Then it runs your JavaScript in a Chrome-based browser to see the finished page.
- Crawling: Googlebot fetches the page and checks robots.txt for blocked files, like scripts and stylesheets.
- Rendering: Google’s Web Rendering Service runs your JavaScript and builds the full page. Pages that return errors, like a 404 or 500, may skip this step.
- Indexing: Google reads the final page, including text, links, and tags like titles and canonicals.
However, the old “two-wave indexing” idea overstates the wait. Vercel and MERJ analyzed more than 100,000 Googlebot fetches. They found that rendering doesn’t create queues lasting several days. Google rendered most pages within minutes. So the real JavaScript SEO risk isn’t the delay. It’s content that fails to load, like APIs that time out or text hidden behind clicks.
Raw HTML vs. Rendered HTML: The Key Idea
Raw HTML is the code your server sends first. Rendered HTML is the page after JavaScript runs. On a well-built site, both versions contain the same text, links, and tags. On a JavaScript-heavy site, the raw version can be almost empty. For example, it may hold just one line, like <div id=”app”></div>.
This gap causes most JavaScript SEO problems. Google reads both versions, while most AI crawlers, like GPTBot and ClaudeBot, read only the raw one. Page size matters too. Googlebot fetches only the first 2MB of an HTML file, so it never reads anything past that point.
| Raw HTML | Rendered HTML | |
| What it is | The first code your server sends | The finished page after JavaScript runs |
| How to view it | Right-click > View Page Source (Ctrl+U) | Right-click > Inspect (F12) |
| Who reads it | Google, Bing, and all AI crawlers | Google, and browsers like Chrome |
| Main risk | Missing content, links, or tags | Content that fails to load or times out |
JavaScript Rendering Methods Explained
Rendering methods decide where your site builds each page: in the browser, on your server, or ahead of time. That choice determines what crawlers can access in your raw HTML. It’s the biggest JavaScript SEO decision you’ll make.
Client-Side Rendering (CSR)
With client-side rendering, the browser builds the page after it downloads the JavaScript. Apps built with React, Vue, or Angular often work this way by default. It suits logged-in areas like dashboards, but AI crawlers see only an empty shell on public pages.
Server-Side Rendering (SSR)
With server-side rendering, your server builds the full HTML page for every visit. Frameworks like Next.js, Nuxt, and SvelteKit support it out of the box. It’s ideal for pages that change often, like product pages with live prices.
Static Site Generation (SSG)
With static site generation, your build tool creates each page once, before anyone visits. A CDN, like Cloudflare or Netlify, then serves those finished HTML files instantly. It fits blog posts, service pages, and landing pages built with tools like Astro or Next.js.
Dynamic Rendering: A Workaround, Not a Fix
Dynamic rendering serves bots a pre-built HTML snapshot while users get the JavaScript version. Google calls it a workaround and not a recommended solution, because it adds complexity and resource demands. Google recommends server-side rendering, static rendering, or hydration for JavaScript-based pages.
| Method | Where the page is built | Full content in raw HTML? | Best for |
| CSR | Visitor’s browser | No | Dashboards, logged-in apps |
| SSR | Server, on every visit | Yes | Product pages, fast-changing content |
| SSG | Build step, before visits | Yes | Blogs, service pages, landing pages |
| Dynamic rendering | Separate server, for bots only | Only for detected bots | Short-term fix for older CSR sites |
JavaScript SEO Best Practices
The best JavaScript SEO practices make sure your content, links, and tags exist before any script runs. These 6 fixes cover the most common problems on JavaScript-heavy sites.
Use Real Links and Clean URLs
Use standard <a href=”/services”> links for every internal page. Googlebot doesn’t click buttons or elements like <div onclick>, so it never finds pages linked that way. Avoid hash URLs like example.com/#/about and use clean paths such as example.com/about
Put Important SEO Tags in the Initial HTML
Place your title, meta description, canonical tag, robots tag, and structured data in the raw HTML. If JavaScript adds or changes these tags later, crawlers may read the wrong version. This also covers Open Graph tags, which control link previews on Facebook, LinkedIn, and Slack.
Return the Right Status Codes and Redirects
Your server must return a real 404 status code for pages that don’t exist. Many single-page apps show a “Page not found” message but still send a 200 status, which creates a soft 404. For moved pages, use a 301 server redirect instead of a JavaScript redirect.
Don’t Block JavaScript or CSS Files
Let Googlebot access every script and stylesheet it needs to render your pages. Check robots.txt for rules like Disallow: /assets/ or Disallow: /static/js/ that block these files. Without them, Google may see a broken layout or missing content.
Use Lazy Loading and Infinite Scroll Carefully
Use native lazy loading, like <img src=”photo.jpg” loading=”lazy”>, instead of scroll-based scripts. Googlebot doesn’t scroll, so content that waits for a scroll event may never load. For infinite scroll, add normal pagination links like ?page=2 so crawlers can reach every item.
Keep JavaScript Light for Better Speed
Smaller JavaScript files load faster and render more reliably. Googlebot fetches only the first 2MB of each file, and the limit applies to uncompressed data. Split code by page, defer third-party scripts like chat widgets and tracking pixels, and aim for an INP under 200ms.
How to Check If Google Can See Your JavaScript Content
You can check what Google sees with 4 simple tests, and 3 of them are free. Start with Search Console, then confirm with a Google search, a browser test, and a site crawl.
Use Search Console’s URL Inspection Tool
Paste your URL into Search Console’s URL Inspection Tool and click “Test Live URL.” Open “View Tested Page” to check the HTML, a screenshot, and any JavaScript errors.
Also, open “View Crawled Page” to see what Google indexed on its last visit. In one test by DebugBear, the live test didn’t cut off a large page at the 2MB limit, suggesting it may not match real crawl behavior.
Search Google for a Line of Your Content
Search site:yourdomain.com “a unique sentence from your page” to confirm indexing. Pick a sentence that loads through JavaScript, like a product description or review.
If your page appears, Google has indexed that content. If nothing shows up, Google may have failed to render the content or hasn’t indexed it yet.
Turn Off JavaScript in Your Browser
Disable JavaScript in Chrome to see your page the way AI crawlers see it. Press F12, then Ctrl+Shift+P (Cmd+Shift+P on Mac), type “Disable JavaScript,” and reload.
If text, menus, or links vanish, your site relies on client-side rendering. That content is invisible to crawlers like GPTBot and PerplexityBot.
Crawl Your Site with JavaScript Rendering On
Run a crawl with JavaScript rendering on to check every page at once. In Screaming Frog, go to Configuration > Spider > Rendering and choose “JavaScript.” This feature needs a paid license.
Then compare it with a “Text Only” crawl of the same site. Pages with big differences depend on JavaScript for their content. Tools like Semrush Site Audit and Sitebulb offer the same option.
Which Setup Is Right for Your Site?
The right setup depends on how often your content changes and which pages need to rank. Public pages need content in the raw HTML, while pages behind a login can use client-side rendering.
By Site Type
Choose a rendering method for each type of page, not the whole site. Blogs and local business sites work best with SSG, while online stores need SSR or ISR for changing prices. Logged-in dashboards can use CSR, since crawlers can’t log in.
| Site type | Best setup |
| Blog or content site | SSG |
| Local business site | SSG or a standard CMS |
| Online store | SSR or ISR |
| SaaS marketing pages | SSG or SSR |
| Logged-in app or dashboard | CSR |
By Framework or Platform
Most modern frameworks support server rendering, but some need the right settings. Plain React and Vue apps render in the browser by default, so public pages should move to Next.js or Nuxt. Site builders like WordPress, Shopify, and Wix already send content as HTML.
| Framework or platform | Default behavior | What to do |
| React (Vite) | CSR | Move public pages to Next.js |
| Next.js | SSR/SSG | Use ‘use client’ only for interactive parts |
| Vue | CSR | Use Nuxt for public pages |
| Nuxt | SSR | Keep ssr: true |
| Angular | CSR | Enable Angular SSR |
| SvelteKit, Astro | SSR / static HTML | Keep the default settings |
| WordPress, Shopify, Wix | HTML from the server | Check heavy apps and plugins |
JavaScript SEO Checklist
Use this JavaScript SEO checklist to confirm crawlers can find, read, and index every public page. Tick each item off, then retest after every major site update.
Rendering
- Public pages use SSR or SSG, not client-side rendering.
- Dynamic rendering is replaced with SSR or SSG where possible.
- Key content shows up with JavaScript turned off.
Links and URLs
- Internal links use <a href=”/page”>, not buttons or onclick.
- URLs are clean, like /about, not /#/about.
- Infinite scroll pages have pagination links like ?page=2.
Tags and status codes
- Titles, meta descriptions, and canonicals are in the raw HTML.
- Structured data and Open Graph tags are in the raw HTML.
- Missing pages return a real 404 status.
- Moved pages use 301 server redirects.
Access and speed
- Robots.txt doesn’t block JavaScript or CSS files.
- Images use native loading=”lazy”.
- Each JavaScript file stays under 2MB uncompressed.
- Third-party scripts like chat widgets load after the main content.
- INP stays under 200ms.
Testing
- URL Inspection displays the full content in the “View Tested Page” secti
- A site: search finds a sentence loaded by JavaScript.
- A JavaScript crawl matches the Text Only crawl on key pages.
How to Talk to Your Developer About JavaScript SEO
Give your developer one clear problem, one fix, and one way to test it. For example, “Category links use buttons, so replace them with <a href> links that show in View Source.” Specific requests like this get done faster than “make the site SEO-friendly.”
If your developer says “Google renders JavaScript fine,” they’re only partly right. Google’s own documentation notes that other search engines may ignore JavaScript entirely. AI crawlers like GPTBot and ClaudeBot don’t run it either, so key content must be in the raw HTML.
Common JavaScript SEO Issues and Their Fixes
Most JavaScript SEO issues occur when content, links, or tags are missing from the raw HTML.
- Pages not indexed: Content loads only after JavaScript runs. Use SSR or SSG for public pages.
- Blank screenshot in Search Console: robots.txt blocks your JavaScript or CSS files.
- Wrong title in search results: JavaScript changes tags after loading. Put final tags in the raw HTML.
- New pages not found: Links use buttons or onclick. Switch to <a href> links.
- Content partly indexed: Text loads on click, scroll, or slow API calls. Load it in the initial HTML.
- “Not found” pages indexed: Missing pages return a 200 status. Return a real 404 instead.
- Missing from ChatGPT or Perplexity: AI crawlers can’t run JavaScript. Serve key content in raw HTML.
- Broken link previews on Facebook or LinkedIn: Open Graph tags load through JavaScript. Add them to the raw HTML.
FAQs
Does Google index JavaScript content?
Yes, Google indexes JavaScript content after rendering it with a Chrome-based browser. Content can still be missed if scripts fail, time out, or need clicks to load.
Can I fix JavaScript SEO without rebuilding my site?
You can fix many JavaScript SEO issues without rebuilding your site. Replace button links with <a href> links, unblock JavaScript files in robots.txt, and move to SSR or SSG when key content relies entirely on client-side rendering.
Do Bing and other search engines handle JavaScript as well as Google?
No, most search engines are less reliable at rendering JavaScript than Google. Google’s own documentation notes that other search engines may ignore JavaScript and miss JavaScript-generated content.
How Much Does a JavaScript SEO Audit Cost?
A small business site often costs a few hundred dollars to audit, while large ecommerce or SaaS sites can cost several thousand. Price depends on page count, framework, and whether developer fixes are included.
Is React bad for SEO?
No, React is not bad for SEO when public pages are server-rendered. The risk comes from client-side rendering, which frameworks like Next.js solve with SSR and SSG.
Can ChatGPT see content that loads with JavaScript?
No, ChatGPT’s crawlers, like GPTBot and OAI-SearchBot, read only raw HTML and do not run JavaScript. Content that appears only after scripts run stays invisible to ChatGPT, Claude, and Perplexity.
What happens if I block JavaScript files in robots.txt?
Google may not render your pages correctly when robots.txt blocks JavaScript or CSS files are blocked. This can cause broken layouts, missing content, and pages that fail to rank.
Is dynamic rendering considered cloaking?
No, Google does not generally treat dynamic rendering as cloaking if bots and users see similar content. Google still calls dynamic rendering a workaround and recommends SSR or static rendering instead.
What is the best free tool to test JavaScript SEO?
Google Search Console’s URL Inspection Tool is the best free option for checking how Google renders a page. Chrome DevTools is also free and lets you disable JavaScript to see what AI crawlers see.
Is server-side rendering worth the cost for a small business?
Yes, SSR or SSG works well for public pages that need to rank and appear in AI answers. Static site generation often costs less than SSR because a CDN serves pre-built pages.
Will AI crawlers start rendering JavaScript in the future?
Some AI crawlers may add rendering, but current research shows none do it consistently. Serving key content in raw HTML is the safest approach for both current and future AI search tools.
Conclusion:
JavaScript SEO follows one core rule: keep your key content, links, and tags in the raw HTML. Google can render JavaScript, but rendering can sometimes fail. Google can render JavaScript, but rendering can fail, and AI crawlers like GPTBot and PerplexityBot skip it entirely. Server-side rendering or static site generation solves most of these issues for public pages.
Real <a href> links, clean URLs, proper 404s, and unblocked JS and CSS files keep crawlers on track. Light JavaScript files help your pages load faster and render reliably. Regular tests with URL Inspection, a site: search, and a JavaScript-off check catch problems early.
Turn off JavaScript on your top 3 pages today, and if key content disappears, send your developer the checklist above.
Need a hand with this?
I do this work for a small number of clients each quarter. A 30-minute call is free and you'll get three specific fixes whether or not we work together.
Usama Habib
AI SEO Specialist & SEO Consultant. I help businesses win visibility in Google and in AI search, and I publish everything I learn as complete topical maps.